You may or may not know that I am an avid litter picker in my spare time. We have a very strong litter picking community in West Lothian (West Lothian Litter Pickers – WLLP) and pick thousands of bags of litter across the county year-on-year. I have volunteered to help out as the Social Media Coordinator for the group and have set up a website and an instagram account for the group (currently learning more about instagram and growing it !).
I’ve had a couple of related projects on the go, behind the scenes, so thought I’d write up a wee blog post covering those and then next steps, with a follow up later. This is at least partly so I don’t forget what I’ve done!
Facebook Group Stats
The main group for WLLP sits on Facebook where it was conceived, I believe, about 7 years ago. There are over 4000 members of that Facebook group and it’s got a lot of activity – people posting interesting links, admin team announcing group picks but mostly people posting up details of their picks – how many bags, pictures of the bags and their dogs, any weird stuff they found, etc. Members jump in to thank people and it really is wonderful to see such a supportive community encouraging each other on.
At my interview for the voluntary position, I’d suggested a monthly newsletter, pulling together the community’s news including bag tallies so I’ve been scratching my head trying to work out how to count bags posted on Facebook.
First I looked at Facebook’s APIs, which looked like it might be a go-er but then found out Meta had closed down the Facebook Group API in 2024 for unclear reasons so that was a no go. I then investigated the ‘insights’ available as a group admin, which looked hopefully, but unfortunately those didn’t give everything and some data was missing (less popular posts for example). I then considered (briefly because it also scared me a bit) an AI agent to manually collect the data from posts once a month but found that it was against Facebook’s Ts & Cs. And being the stickler for Ts & Cs you know I am, I didn’t even try it. So what was left? I wondered whether a browser add in might work and I got Claude to help me develop one. The add-in does a manual grab of all the post text. That means, I still need to go into FB myself and scroll, not ideal, but it only takes a few minutes to do a month and is accurate, unlike the insights data. I think this is the only option available right now but if you have a more cunning plan, please do let me know!
The add-in creates a JSON file with all the data and then I run a python script over the data which splits the data appropriately and adds it to an Excel spreadsheet master I have. This has been interesting and gives stats about bag numbers for anyone who posts. If the person posts a picture without giving a bag count, my add, a python script adds it to a ‘needs reviewed’ tab which I go in and manually check it and update. I then rerun the python script which takes the reviewed content and moves it back to the main spreadsheet and then I can make graphs/pull numbers and counts. I am able to share a dashboard with the admin team giving things like:
- Bags this month and since we started counting
- How many new members we have
- Total number of members
- How many of the bags were collected at group picks vs individual picks.
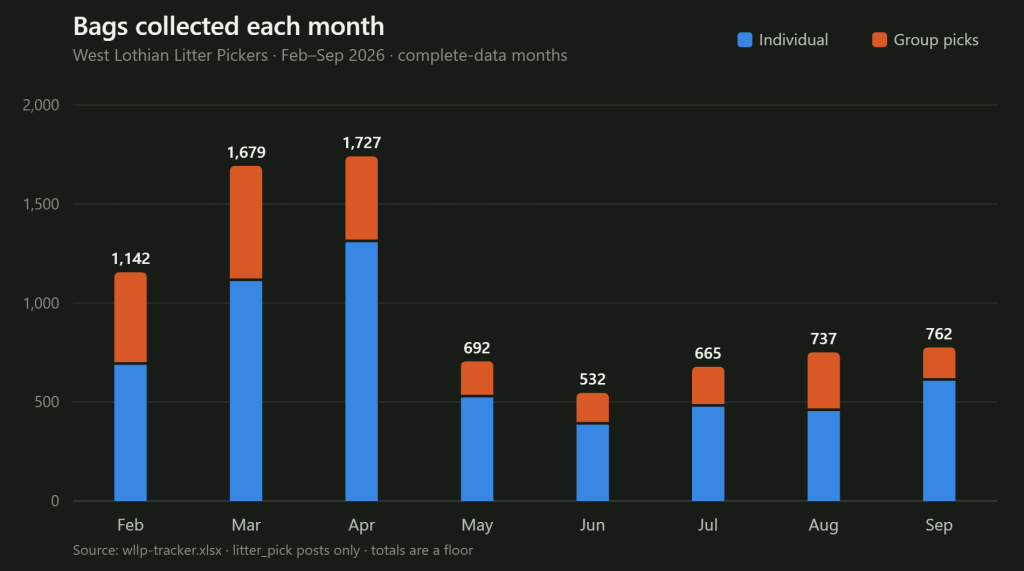
I can only go back to a date in February as FB won’t let me scroll back any further than that but you can see the data is interesting (you can see when we had a big Spring Clean Scotland campaign, run by Keep Scotland Beautiful, in which West Lothian came in 2nd place as the county with the 2nd highest number of picks in Scotland.
Litter picking audit
The other project, I started more recently, after the WLLP AGM and Emma, the speaker from KSB was talking about the results of the litter audits they do. Effectively someone categorises and counts the litter picked. This is interesting because it shows trends and counts. However, if you’ve tried litter picking, you’ll know that carrying a clipboard and marking each bit of litter you pick would be a complex juggling act and would massively reduce the amount of litter you were able to pick (or take much longer for you to pick the same quantity). As I mentioned in a previous blog post, there are some organisations starting to use AI for litter recognition/audits but that got me thinking about whether there might be a cheaper/easier way to do this.
For the past 2 weeks, when I’ve been out litter picking, I’ve been getting some funny looks. I’ve been narrating my pick as I go, recording, and then transcribing. I then pass the transcription to AI to correct the obvious transcription errors and then I’ve been rather painstakingly correcting any others that are wrong. My plan is to count the brands wherever possible too. At first I used my cheap ear buds as a microphone. This wasn’t great, audio quality was very poor. Then I bought a cheap clip-on, wireless mike specifically for outdoor use (about £12) and used that instead. The quality of the recording is now much better.
I am using Apple’s Voice Memos to record and it automatically generates a transcript but it is fairly limited. The transcript isn’t brilliant (unsurprisingly given the brand names I’m using and also the scottish accent!) but the biggest limitation is that it gives you no timing information so it’s hard to manually correct if you need to but I found a transcription application called ‘Buzz‘. It’s open source and free. It uses OpenAI’s Whisper to do the transcription and you can output as text/SRT or VTT so you can get the timings. You can also use different models – I tried Whisper (Tiny) at first which didn’t work at all but Whisper (Medium.en) was much better and you can actually provide a prompt before you run the transcript which helps (‘I am litterpicking in scotland and I’m cataloguing what I find. Common things like Monster Cans, McDonald’s take away food…..’). It takes a while to run but it runs on my own computer and I believe I can probably train it on the vocabulary I’d regularly use to cut down the post processing of my audio files so those are my next steps and I’ll report back when I’ve done that.
I now have a dashboard covering 4 picks which gives me total numbers of items picked, top 20 brands, numbers per categories etc. Clearly a long way to go but it’s been really interesting.
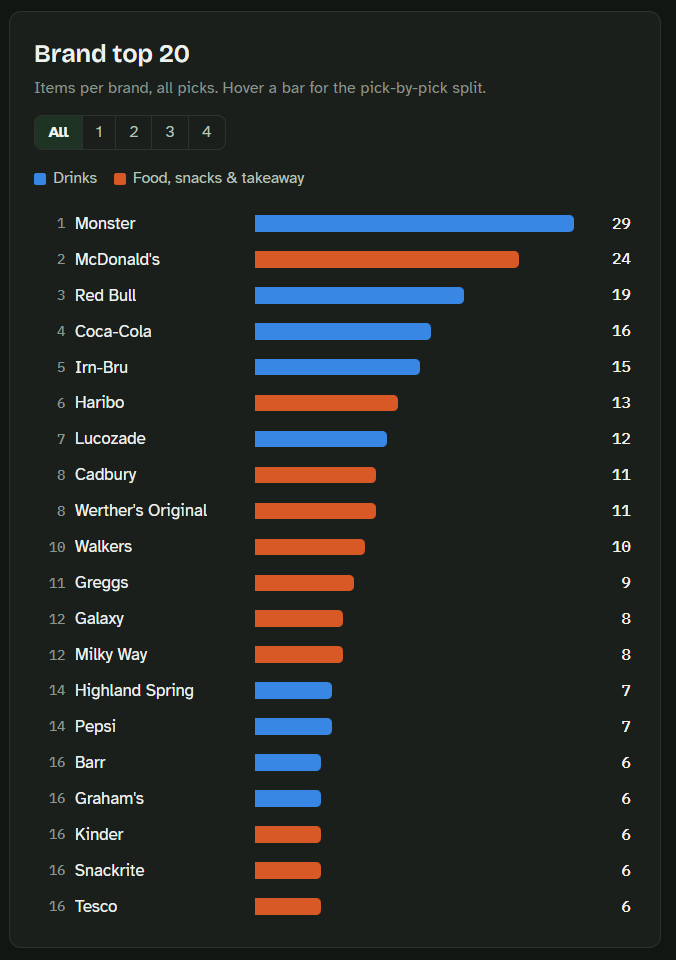
Of course, because I’m always recording, everything is captured. So after I transcribed the latest pick and asked ChatGPT to analyse the transcription, it gave me a spreadsheet summarising transcript vs correction and also said …
‘And falling down the embankment and immediately resuming the litter census with a dusty arse is admirable dedication to the methodology.

‘